In today’s digital era, data drives every organization. Every day, organizations generate massive amounts of data, from personal information and financial records to intellectual property. Organizations often struggle to organize, protect, and manage this volume of data. Data classification is the solution to this problem.
Categorizing data by sensitivity and the impact of loss or theft helps organizations organize, protect, and manage it. Here, we’ll explain the meaning and different types of data classification, and help you understand how it differs across industries.
Key Takeaways: Data Classification Framework Best Practices for a Business
- Use categories such as Public, Internal, Confidential, and Restricted to define clear levels.
- Apply classifications consistently when data is created, collected, or received.
- Always consider data sensitivity and account for personal, financial, health, payment, and business-critical data.
- Restrict access to sensitive data based on roles and business needs.
- Use consistent and clear labels to show how data should be handled.
- Define requirements for storing, sharing, retaining, and deleting data by setting handling rules.
- Use classification and DLP tools to identify sensitive data; automation is faster.
- Review and update classifications when data sensitivity or requirements change.
- Train staff properly so they understand classification and handling requirements.
- Monitor, track, and audit access and classification changes for accountability.
Why Should Data Be Classified?

Data classification forms the foundation of data security, helping organizations manage and protect their data. The process categorizes data by sensitivity and importance and helps ensure compliance with regulations like GDPR and HIPAA. It helps prevent data breaches and avoid overspending on protecting less sensitive data.
The key reasons data classification is important include:
A. Improves Security
Data classification helps identify sensitive information, enabling organizations to safeguard it with appropriate security measures, access controls, and monitoring to protect critical data from breaches, theft, or loss.
B. Supports Regulatory Compliance
The process helps organizations meet legal and regulatory obligations by ensuring sensitive and confidential data is handled in accordance with specific guidelines, like the General Data Protection Regulation (GDPR) and HIPAA.
C. Helps in Efficient Data Management
Organizing data into categories helps handle and process information more efficiently. Data classification makes it easier for organizations to locate, manage, and secure different types of information.
D. Reduces Costs
By implementing data classification methods, organizations can focus on protecting the most important data. It helps businesses decide the level of protection for different types of data by classifying them based on importance and avoiding overspending on less sensitive data.
E. Improves Awareness
Data classification improves awareness of different data types and the need to protect sensitive information. Proper classification enables a stronger data security culture.
F. Helps with Data Mapping
The classification process helps organizations map out their complete data landscape. It helps them clearly understand their data sets and the risks associated with them.
G. Maintains Trust and Reputation
Proper classification ensures effective protection of customer data and business data. By protecting such confidential data, companies can preserve trust and safeguard their brand reputation from the negative impacts of data compromise.
The benefits of data classification are enough to help you understand why companies often implement such methods.
What Are the Different Data Classification Types or Levels?
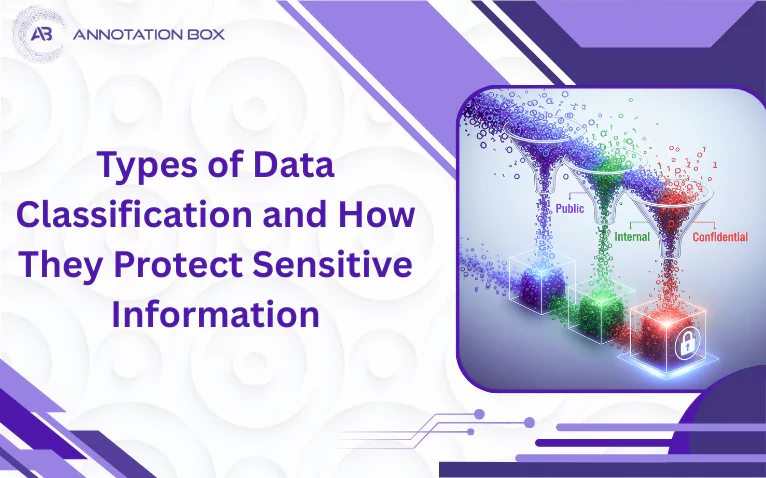
Data classification types are based on the sensitivity and access requirements of each data type. Wondering what are the common data classification levels? The following are the common data classification types:
A. Public Data
Public data is the least sensitive data. This information is freely available to the general public and does not require protection. Examples of public data include marketing materials, public website content, and price lists.
B. Internal Data
This data is for internal use by employees only. The data requires some level of security. However, unauthorized disclosure may lead to embarrassment or a short-term loss of competitive advantage. Examples of internal data assets include employee handbooks, sales playbooks, and organizational charts.
C. Confidential Data
Confidential data is sensitive data that, if compromised, can cause harm to the company, its customers, partners, or employees. It requires clearance for access and is therefore considered sensitive. Data classification examples of confidential data include vendor contracts, employee salaries and reviews, and certain customer information.
D. Restricted Data
Restricted data is the most sensitive data of all the types. It includes personal information or data that can cause significant legal, financial, or reputational damage if compromised. Examples of restricted data include personally identifiable information (PII), protected health information (PHI), credit card details, and trade secrets.
Data classification helps organizations understand the data type and apply security measures accordingly. Businesses often use data classification services to ensure data is classified correctly based on its content.
Data Classification Examples: What Examples Should Be Assigned to Each Data Classification Level?
- In the public level, common data classification examples include marketing materials, press releases, job postings, published research, public website content, product datasheets, SEC filings, rate sheets, and terms & conditions.
- At the internal level, data collection services and classification services usually categorize internal memos, employee handbooks, training manuals, company directories, IT helpdesk guides, internal policies, non-confidential emails, and internal project plans.
- Financial statements, legal contracts, supplier contracts, customer lists, pricing lists, business strategies, proprietary designs, some HR records, student education records (FERPA), and IT service management data are often classified as confidential or Business-sensitive data.
- When it comes to government IDs (SSN, passport, driver’s license), credit card numbers (PCI), bank account numbers, biometric data, passwords/credentials, protected health information (HIPAA), trade secrets, source code, M&A plans, and government intelligence/law-enforcement data, they are classified as restricted or highly sensitive data.
Data Classification Levels vs. Data Classification Methods: What’s the Difference?
|
Classification levels |
Classification methods |
|
Define how sensitive the data is |
Define how the data is classified |
|
Public, Internal, Confidential, Restricted |
Content, Context, User |
|
Determine protection requirements |
Determine the approach used to assign the label |
The Different Types of Data Classification Methods

Data classification methods are divided into three categories based on the type of data, where it is, and who is responsible for it. Here are the three different types of data classification methods:
A. Content-Based Classification
This content based data classification method analyzes data or the actual content of the files and documents to understand their classification. It helps tag the data on the basis of the sensitive data the file or document has, like personally identifiable information (PII), or credit card numbers.
B. Context-Based Classification
The context based data classification method examines the metadata around the data pipeline, which includes its source application, location, creation time, and owner.
C. User-Based Classification
This user based data classification method relies on users to manually classify the data based on their knowledge and discretion. They assign labels like ‘internal use’ or ‘for your eyes only.’
Organizations use any of the three methods to classify vast amounts of data. The current AI-powered data classification process differs from the traditional approach. The following section will help you understand how they differ.
A Comparison Between Traditional vs. Modern Data Classification
Data classification strategies fall into two broad categories: traditional and modern. Here’s an insight into how these strategies differ from one another:
|
Characteristics |
Traditional Strategies |
Modern Strategies |
|
Approach |
Primarily manual, with IT administrators or data owners tagging files based on predefined rules or regex patterns |
Automated and AI-driven data classification |
|
Data Types |
Focused on structured data |
Handles both unstructured and structured data |
|
Scalability |
Limited and not scalable |
Highly scalable |
|
Accuracy |
Prone to human error |
More consistent and accurate |
|
Context |
Lacks context |
Aware of the context |
Modern data classification tools can be more effective for data loss prevention and proper data classification. They can group raw data for better understanding and apply security measures more effectively.
What Are the Different Types of Data Classification Schemes?

Data classification schemes are structured systems or frameworks that categorize data based on criteria such as sensitivity, confidentiality, compliance requirements, format, or usage within an organization. Here’s a brief explanation of the different schemes:
A. Sensitivity-Based Schemes
Under sensitivity based data classification scheme, data is classified based on its confidentiality and risk. Data types may include public, internal, confidential, and highly confidential/restricted. These schemes help organizations implement appropriate security controls based on risk levels and regulatory requirements. Organizations that handle user-generated content often use content moderation services to filter posts and comments.
B. Compliance-Based Schemes
In this case, the data is grouped to meet regulatory standards like PII (GDPR/CCPA), PHI (HIPAA), or financial data (PCI-DSS). This data architecture helps in legal protection and simplifies audits and reporting.
C. Format-Based Schemes
Here, categories are based on data structure, such as structured, semi-structured, and unstructured data. This helps with efficient storage, retrieval, and analysis, especially for advanced systems and machine learning models.
D. Context-Based Schemes
The scheme classifies data by meaning and business use. Context-based data classification uses AI to analyze the context, such as user behavior or transaction history, for dynamic, real-time sorting and deeper business insights. Businesses often use data annotation services to classify data.
E. Government and Commercial Schemes
Data is classified using schemes like top secret, secret, confidential, and unclassified. Commercial organizations often use categories like public, internal, confidential, and restricted. Hybrid or custom schemes combine elements to meet industry-specific requirements.
How to Classify Data: Step-by-Step

From data classification to data processing services, organizing data by sensitivity and risk helps apply and maintain privacy and policy controls.
Step 1# Identify and Inventory Data
To start, data classifiers discover and catalog data where it lives today, such as file shares, cloud storage, databases, SaaS apps, endpoints, or backups. Once they identify the data, they can use automated tools to scan for patterns such as PII, PCI, and PHI.
Step 2# Determine Data Sensitivity
The next step is to understand and evaluate the impact of a data leak, alteration, or destruction. This is when they organize the data as per the 4 tiers.
Step 3# Identify Regulatory and Business Requirements
Then the classifiers list the applicable laws, add contractual and client obligations, and define handling rules (retention, encryption, access limits, breach-notification duties).
Step 4# Assign a Classification Level
Now create a classification matrix with concrete examples by level and domain (HR, Finance, Health, Education, Tech), and tag data assets and files with the assigned level (metadata labels, DLP tags, folder naming).
Step 5# Review and Update Classifications Regularly
The classifiers conduct regular audits to catch compliance drift and update categories as the business evolves.
What Should a Data Classification Policy Include?
A data classification policy should define classification levels, give concrete examples, map each level to security controls, and embed regulatory handling rules (HIPAA, GLBA, FERPA, CCPA/CPRA, PCI DSS) so teams know exactly how to treat each data type.
The core component of the policy includes:
- Why the policy exists, what data it covers, and who must comply with it.
- It must also list the roles and responsibilities of people involved in the work, such as data owners, custodians, users, privacy/security officers, and their duties for classification, approvals, and exceptions.
- From classification schemes to examples for each data classification level and domain, the policy should cover them all.
- The policy must map access control, encryption, logging/monitoring, DLP, retention/deletion, and sharing/transfer rules to each level.
- Whether data must comply with HIPAA, GLBA, FERPA, CCPA/CPRA, or PCI DSS, the policy must lay out which laws/standards apply to each data set.
- Labeling and handling procedures also include how to tag data (metadata, headers, DLP labels), and how to store, share, print, and dispose of each class.
- From exception requests, approval, and time limits to mandatory training, role-based guidance, and quick-reference job aids, data classification policies include it all.
- Lastly, it must include how you measure compliance and how often you review and update classifications and policies.
Regulations Referenced in a Data Classification Policy
- HIPAA — Health Insurance Portability and Accountability Act
- GLBA — Gramm-Leach-Bliley Act
- FERPA — Family Educational Rights and Privacy Act
- CCPA — California Consumer Privacy Act
- CPRA — California Privacy Rights Act
- PCI DSS — Payment Card Industry Data Security Standard
How Does Automated Data Classification Compare with Manual Classification?
Automated data classification is faster, more consistent, and scalable for large, dynamic environments, while manual classification is better for nuanced judgment, policy design, and edge cases. Most mature programs combine both: automation to discover and tag at scale, and human review to validate, govern, and handle exceptions.
Before we end this discussion, it’s important to understand how data classification differs across industries and how organizations implement data management strategies to spot and prevent potential security breaches.
Understanding How Data Classification Is Different for Various Industries

A. Healthcare
In healthcare, data is classified by sensitivity and compliance requirements. This is crucial for Protected Health Information (PHI). The industry classifies patient records and diagnostic data as restricted or confidential to meet HIPAA regulations for access, handling, and sharing.
B. Financial Services
The financial sector prioritizes protection for client data (PII), transaction records, and payment data. These categories include public, internal, confidential, and restricted. PCI DSS, SOX, and other compliance frameworks require proper classification for audit and reporting. Strategic data, such as trade secrets and merger plans, is highly restricted to reduce risk.
C. Government and Public Sector
Government and public sectors use schemes like unclassified, confidential, secret, and top secret, following the national security laws and executive directives. Sensitive government data is handled under the highest restriction, while public data is accessible to all.
D. Commercial Organizations
Commercial data classification is generally less standardized. The customization is mostly based on business needs, proprietary data, and user privacy. Classification levels typically include public, internal, confidential, and highly confidential/restricted. Sometimes organizations customize classification for cloud security, marketing, and HR records. The process follows regulatory schemes and protection rules for specific data categories. Businesses must implement proper security protocols to safeguard private data, such as customer information.
Endnote:
Data is everywhere, but it is essential to understand which data is important and needs protection and which is not. Data classification categorizes information by importance and applies appropriate security protocols. It helps businesses and organizations understand the importance of each piece of data and develop data management strategies.
Understand how classification can be used to classify and protect data according to data protection laws for a better and more secure data environment. Also, understanding how machine learning data annotation supports the process is crucial.
Frequently Asked Questions
What is data classification, and why is it important in businesses?
Data classification is the process of systematically categorizing an organization’s data based on its sensitivity, importance, and other criteria used to determine appropriate security measures and handling policies.
This process matters for businesses because it helps maintain data security by enabling targeted protection of sensitive information and supports regulatory compliance by helping meet requirements like GDPR and HIPAA.
What is a data classification level?
A data classification level is the category that organizes and ranks data based on its security, value, and the risk associated with unauthorized access, use, or disclosure.
What Are the 4 Types of Data Classification?
The 4 common types or levels of data classification are:
- Public data – This is intended for public access and needs minimal protection
- Internal (or private) – Internal data is for private use only
- Confidential – This is sensitive data that requires restricted access to protect privacy or business interests
- Restricted – This data demands the highest security controls because of its critical nature
How does data classification help protect sensitive information?
Categorizing data by sensitivity helps organizations apply tailored safeguards such as access controls, encryption, and monitoring. This process supports effective data protection and helps prevent unauthorized access. It also ensures that sensitive data, such as personal information or trade secrets, is protected against breaches or leaks.
What Are the 3 Main Types of Data Classification?
The three common methods used to classify data are:
- User-based data classification – The classification depends on the user while creating the data
- Context-based data classification – It uses metadata or environmental data, like origin or user role, to determine sensitivity
- Content-based data classification – In this method, the data is analyzed directly to classify automatically or manually
What happens if data is not properly classified?
If data is not properly classified, it can expose sensitive information, increase breach risk, create operational inefficiencies, lead to regulatory violations, hamper data retention, and cause reputational damage. Without clear classification, organizations may overspend protecting less sensitive data or fail to allocate resources where they are most needed.
Are public, internal, confidential, and restricted data classification levels universal?
No. Public, Internal, Confidential, and Restricted are the most common levels in commercial organizations, but they are not universal. Governments use levels such as unclassified, confidential, secret, and top secret, and commercial data classification is generally less standardized, with levels customized to business needs.
Is automated data classification more accurate than manual classification?
Automated data classification is generally more consistent, less prone to human error, and scales better for large, dynamic environments. Manual classification is better for nuanced judgment and edge cases. Most mature programs combine both: automation discovers and tags data at scale, and human review validates and handles exceptions.
How does content based data classification work?
Content based data classification analyzes the actual content of files and documents and tags them based on the sensitive data they contain, such as personally identifiable information (PII) or credit card numbers.
What is data classification based on in a business context?
In a business context, data classification is based on sensitivity, business value/impact, and regulatory/legal obligations, then expressed as labels (e.g., Public/Internal/Confidential/Restricted) that drive access, storage, and handling rules.
How to classify enterprise database assets?
To classify enterprise database assets, identify and inventory the data, determine its sensitivity, identify regulatory and business requirements, assign a classification level, and review classifications regularly.
Want To See My Profile — Click Here Ankit Sureka
- Types of Data Classification and How They Protect Sensitive Information - September 23, 2026
- How Image Annotation Improves AI Model Accuracy and the Role of AI Model Training? - October 20, 2025
- The Impact of High-Quality Image Annotation on Facial Recognition AI - July 21, 2025